Choosing between object storage and local storage for VPS file uploads depends on how your application runs, how quickly files grow, and how you recover them. Local storage can be a practical choice for one application server with predictable usage. Object storage becomes more useful when several application instances need the same files or upload growth should be independent of the VPS disk.
The decision also changes permissions, file delivery, backups, and deployment. This guide compares the two approaches and gives you a migration plan for existing uploads.
What is the difference between local and object storage?
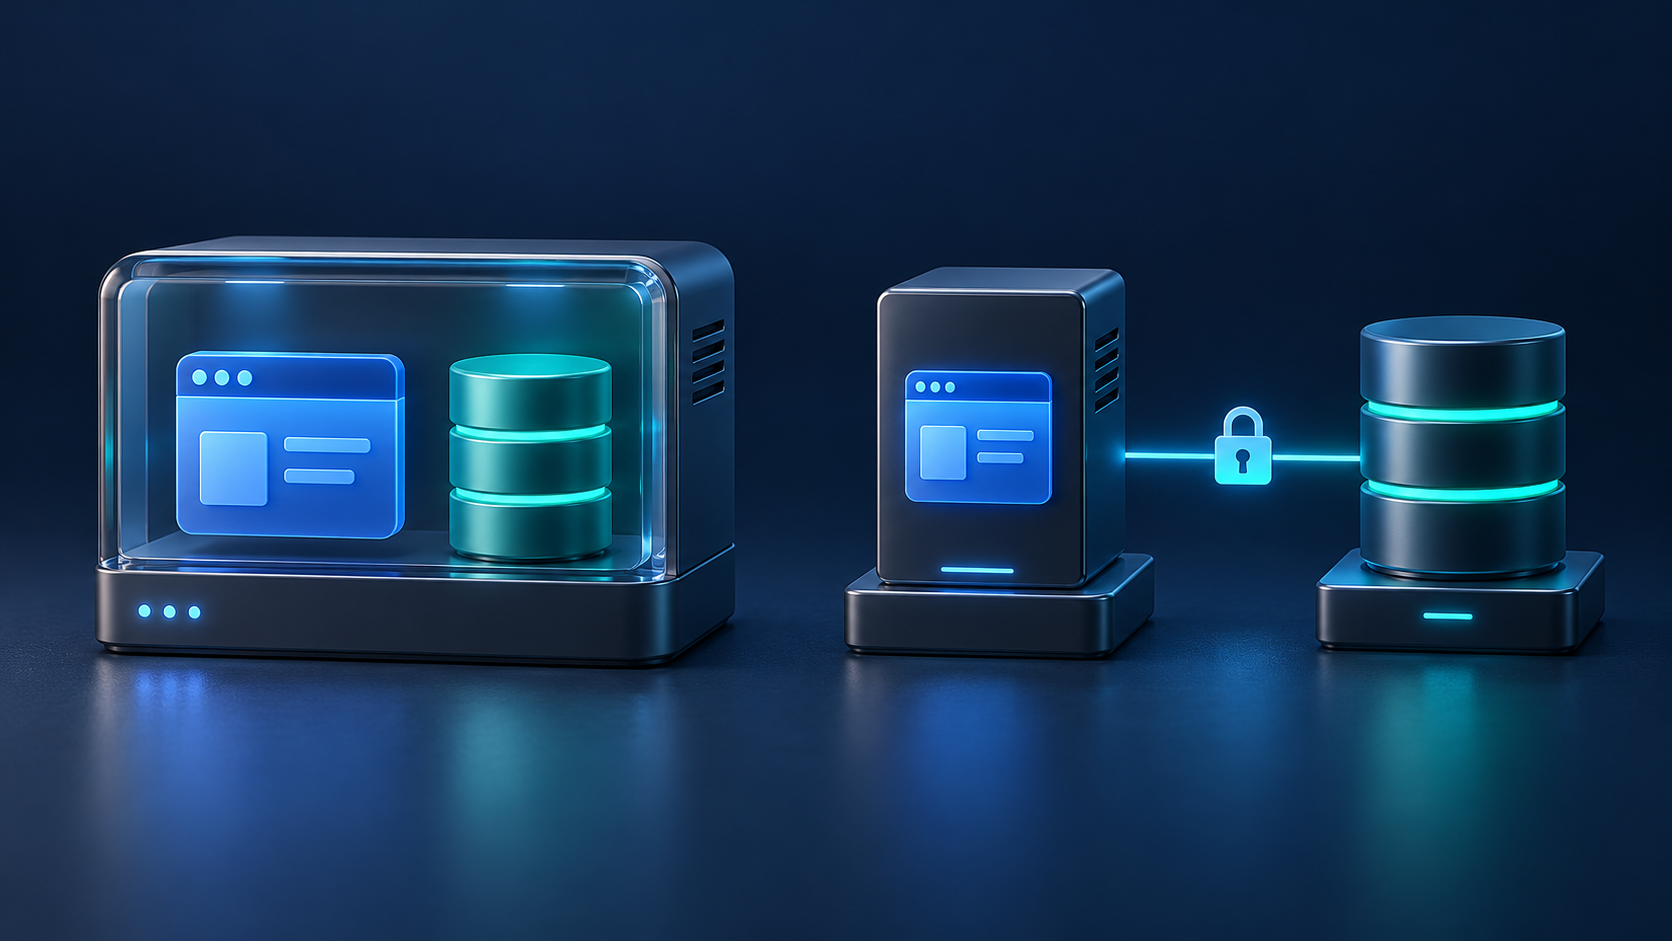
Local storage means your application reads and writes files through the filesystem available to its VPS. The underlying disk may be virtual or provider-managed, but the application works with paths, directories, and filesystem permissions.
Object storage exposes files as objects through an API. Each object has a key and metadata inside a container, commonly called a bucket. For example, Amazon S3 general purpose buckets use object keys; slash-separated names can look like folders without being ordinary filesystem directories.
A third option, shared file storage, exposes a filesystem to multiple machines. It has different access semantics and operating requirements. Do not assume that mounting an object-storage bucket makes it behave identically to a local disk or shared filesystem.
| Decision | Local VPS storage | Object storage |
|---|---|---|
| Application access | Filesystem paths and permissions | API requests, object keys, and access policies |
| Multiple app servers | Requires an explicit sharing or synchronization design | Authorized instances can use the same object service |
| Capacity planning | Monitor disk space, inodes, and expansion options | Monitor stored data, service limits, requests, and transfer |
| File delivery | Through the web server or application | Through an application, authorized URL, or delivery service |
| Failure dependency | Files depend on the VPS and its storage arrangement | Files depend on the object service, network, and permissions |
| Recovery | Back up files and test restoration | Configure retention and recovery; test restoration |
When local storage is a reasonable choice
Keeping uploads on the VPS can work well for a small application with one serving instance, limited file growth, and a tested backup routine. It also avoids introducing a storage API dependency into every operation that needs a file.
Keep persistent uploads outside directories replaced during deployment. Separate temporary processing files from originals you must retain, and define a cleanup policy for both. A successful release should never depend on accidentally preserving an old release directory.
Review disk space and inode usage, upload limits, ownership, and restore time. If the server disappears, identify where the recoverable copies live and how the replacement application finds them. Increasing the VPS disk is a capacity change; it does not establish a backup strategy.
When to move uploads to object storage
Consider object storage when uploads must survive routine replacement of application instances, several workers need the same originals, or media growth forces frequent VPS disk upgrades. A shared API can remove the need to keep an identical uploads folder on every web server.
For example, imagine a document service running on two application nodes. A customer uploads through node A, then a later request reaches node B. If the only copy is on A's local disk, B needs an additional way to retrieve it. Object storage is one solution; a carefully designed shared filesystem is another.
Moving files also adds dependencies. Test behavior when the storage endpoint times out or access credentials expire. Avoid silently switching to an unrelated local upload directory during an outage: users may receive success messages for files other instances cannot find.
Choose how uploads reach storage
There are two common routes. In an application-mediated upload, the browser sends the file to your app and the app writes it to storage. In a direct upload, the app authorizes an operation and the browser sends the bytes to the object service.
S3 presigned upload URLs support a specific upload without exposing the server's storage credentials to the browser. In S3, uploading to an existing key replaces the current object, so issue unique application-generated keys instead of allowing a client to choose a destination belonging to another user.
A practical direct-upload workflow is:
- The application checks the user's identity, permissions, and upload allowance.
- It creates a pending upload record and authorizes a short-lived upload to a unique private staging location.
- The browser uploads the file, then reports completion to the application.
- The server independently verifies the stored object and runs the required content checks.
- The application marks an approved file ready and exposes only the approved object or version.
The final step must bind approval to the bytes that were checked. Use an appropriate version identifier or promote validated content to a separate destination that the upload authorization cannot overwrite. A successful browser callback alone is not proof of a safe or complete upload.
Browser uploads may also require CORS configuration for the storage endpoint. Configure the required origins, methods, and headers. CORS governs browser access behavior; storage permissions still apply.
Keep private files private throughout delivery
Classify files before choosing their delivery path. A public product image and a customer's invoice should not inherit the same visibility just because both use the same storage driver.
For private downloads, check authorization before returning file bytes or generating an access URL. S3 presigned URLs are bearer tokens: anyone holding a valid URL can use its permitted operation. They can be reused until expiry, subject to the underlying credentials and policies. Protect them from unnecessary logging and sharing.
Apply upload checks regardless of the storage destination. The OWASP File Upload Cheat Sheet recommends controls including authorization, allowed file types, generated filenames, size limits, and appropriate content inspection. Do not trust a client-supplied filename or Content-Type header as proof of what the file contains.
For local uploads, prevent execution and unintended direct exposure. For object storage, restrict application credentials to the required operations and locations. Review the public delivery or CDN configuration separately so that a private origin does not become publicly readable through another route.
Budget for requests, transfer, and processing
Compare the complete workload rather than only the advertised storage price. The Amazon S3 pricing model, for example, separates storage, requests, retrieval, transfer, and optional management features. Other providers have different inclusions and charging rules.
Estimate stored originals, generated thumbnails, retained versions, monthly downloads, and upload activity. A modest collection of frequently downloaded files can have a very different cost profile from a large archive that is rarely accessed. Include any CDN and processing service you plan to use.
Also measure latency with representative files. Avoid repeatedly listing an entire bucket to render a page when the application already knows the required keys. If a processing library needs a local file, download to bounded temporary storage and clean it up reliably; moving originals away does not eliminate every local disk requirement.
Plan retention and failed-upload cleanup
Decide how long to retain originals, previous versions, rejected uploads, and abandoned work. S3 Versioning can help recover from overwrites and accidental deletion when enabled, but versions consume storage and retention rules affect what remains recoverable.
Check who can permanently delete retained data and whether your recovery design needs a separately protected copy. Keep the database records that identify file owners and object locations in the recovery plan as well. Recovering bytes without the associated authorization records may not restore a usable application.
For large uploads, S3 multipart uploads allow separate parts to be uploaded and completed as an object. Incomplete uploads require completion or abort to release stored parts; configure a suitable cleanup process. Test interrupted uploads and recovery instead of assuming every started transfer finishes.
Migrate existing uploads with a reversible cutover
Use a written migration plan that accounts for changes while copying. For a manageable application, a short upload maintenance window may be easier to verify than introducing temporary dual-write behavior.
- Inventory: map existing files to database records, owners, visibility, size, and destination keys.
- Prepare: configure a private destination, restricted access, retention, and the application's new storage path.
- Copy and verify: compare the inventory, file sizes, and appropriate content checksums. S3 supports checksum-based integrity verification; use the correct method for your upload tooling.
- Reconcile changes: pause mutations or explicitly account for new uploads, replacements, and deletions that occurred during the copy.
- Switch and exercise: test authorized downloads, denied access, new uploads, processing jobs, and deletion through the application.
- Retain a rollback path: keep the old data for an agreed period and document how files created after cutover would be preserved if you revert.
Store a durable storage identifier and object key where practical, generating delivery URLs when needed. Expiring download URLs should not become the permanent location recorded in your database.
Check framework and hosting integration
A framework adapter can simplify switching storage backends, but it does not prove every operation behaves identically. Laravel's filesystem documentation covers local and S3 drivers, visibility, and temporary URLs. Check the documentation for your installed version and test the operations your application actually uses.
For Laravel deployments, pair this storage review with the Ubuntu, Nginx, and PHP-FPM deployment guide. Review Core Panel's VPS control panel overview and current documentation when evaluating hosting administration. Storage integration remains an application design decision. Core Panel is currently pre-production; evaluate it on an isolated non-production server while verifying applicable readiness controls.
Frequently asked questions
Is object storage always better than local storage?
No. Local storage can meet the needs of a small single-server application. Object storage becomes attractive when shared access, independent capacity growth, or replacing application instances matters enough to justify the additional integration.
Can object storage replace my database disk?
Do not treat an object API as a drop-in disk for a running database. Use storage supported by the database for its active data. Object storage can still hold backup artifacts when your backup tooling supports it.
Does object storage make uploads automatically safe?
No. The application still needs authorization, file validation, appropriate processing, and controlled delivery. Direct uploads should remain unavailable to readers until the required checks pass.
Should every application file move to object storage?
No. Identify persistent user content separately from release assets, caches, and temporary processing files. Choose storage for each role, and document which data must be backed up or can be recreated.